Building GrammarLens
From a one-week MVP to the App Store: defining the problem when every AI call has a price.
GrammarLens is an iOS app for English learners who became fluent through games, series and friends, but can't reliably apply the grammar an exam like IELTS asks for. It generates practice around your own mistakes and explains them in plain language, not rule names.
I built it alone: the research, the PRD, every product decision, and the code, written with AI coding agents that I directed through written decision reports. It started in July 2026 as a one-week MVP tested with seven people. Over the next two months it became a subscription product: a free Daily Test graded on the device, paid Topic Practice that an AI model generates and grades, and a monthly habit layer on top.
Version 1.0 was submitted to App Store review on 24 September 2026. It is not approved yet, and there is no user data. So this is a record of decisions, not results.
Looking back, the useful work was rarely solving a problem faster. It was noticing that the problem in front of me wasn't the real one. Each decision below follows the same shape: what the problem first looked like, what it turned out to be, what I chose, what it cost, and how I'll find out whether I was wrong. Every figure is marked as measured or estimated.
-
July: the MVP week
- 19 Jul First commit
- 20–25 Jul MVP week: first build, interviews, iteration 2
-
August–September: to the App Store
- 24 Aug Onboarding, Home and Premium screen
- 2 Sep Free and paid split
- 6 Sep API key moved behind a server proxy
- 14 Sep First run on a physical iPhone
- 15 Sep Paywall leak closed; free tier defined
- 19 Sep Monthly Climb moves into the first release
- 21–22 Sep Cap 10 → 5, AI permission, fixed first test, paywall after the climb
- 23 Sep Merged; first TestFlight build
- 24 Sep Submitted to App Store review
Show chart data
| Date (2026) | Event |
|---|---|
| 19 Jul | First commit |
| 20–25 Jul | MVP week: first build, interviews, iteration 2 |
| 24 Aug | Onboarding, Home and Premium screen |
| 2 Sep | Free and paid split |
| 6 Sep | API key moved behind a server proxy |
| 14 Sep | First run on a physical iPhone |
| 15 Sep | Paywall leak closed; free tier defined |
| 19 Sep | Monthly Climb moves into the first release |
| 21–22 Sep | Cap 10 → 5, AI permission, fixed first test, paywall after the climb |
| 23 Sep | Merged; first TestFlight build |
| 24 Sep | Submitted to App Store review |
1. The assumption research broke
I started as the user. During IELTS preparation I kept making the same handful of mistakes: gerund versus infinitive, modals, modal past forms. I could produce a correct sentence by feel without being able to explain why it was correct. Fluency from immersion, grammar knowledge left implicit. IELTS asks for the explicit kind.
That gave me a problem statement. It did not give me a product, and my first version encoded an assumption I hadn't noticed I was making: that naming the grammar rule is a feature. The app surfaced rule names as primary labels.
Seven people disagreed, across four interviews and three usability tests. One of the interviews was with myself; I flagged it in the PRD, and I'm flagging it here. One participant pointed out that being told to "use Past Perfect Continuous" meant nothing to him, even though he uses that structure every day. Another said terms like "noun clause" were harder to understand than the mistake they described.
- First framing
- Learners don't know the grammar rules.
- Actual problem
- They already use the rules. The rule names are what's in the way.
So I inverted it. Plain-language explanation first, the rule name demoted to a secondary caption for anyone who wants it. In the three usability tests that followed, all three participants praised the plain-language feedback without being asked about it. It is the strongest and most repeated finding in the project.
The same rounds killed a second assumption. My question mix was mostly fill-in-the-blank and multiple choice, the formats that are easiest to build and score. Five of seven people rejected them. One participant explained it better than my own reasoning did: with options, she said, she would have guessed; without them, she had to prove she actually knew.
Free-text answers cost more to score and are harder to get right. I kept them anyway, because the evidence said the cheap format was measuring the wrong thing.
Seven people is not a sample. It was enough to show me which way I was wrong, and that was what I needed at that stage.
2. Decisions under a per-call price
GrammarLens calls a language model for every exercise it generates and every answer it scores. That makes cost a product constraint, not an engineering detail. It is also why defining the problem mattered so much: in this product, the wrong framing isn't only a worse feature, it's a recurring bill.
Show chart data
| Flow | Steps | Model calls |
|---|---|---|
| First Daily Test | Hand-written questions, then answers graded on the device | 0 |
| Daily Test | Model generates questions and explanations (model), then answers graded on the device. Finishing a test prepares tomorrow's set in the background. | 1 |
| Topic Practice | Model generates questions (model), then user answers, then model grades and explains (model) | 2 |
What to give away
- First framing
- How many free sessions before the paywall?
- Actual problem
- Which parts of the product cost money every time someone uses them?
The usual answer to the first question is a limited version of the paid product. But Topic Practice calls a language model twice per session, once to generate and once to grade. A free, unlimited version would scale cost with users and revenue with nobody: roughly $90–270 a month at 100 daily users estimated, a rough figure I worked out at the time. A hard paywall in front of everything had the opposite problem. Nobody would ever meet the plain-language feedback that every tester had praised.
So I built two structurally different modes instead of one mode with a limit. The free Daily Test makes a single generation call and grades answers on the device, with no model involved. The paid product is Topic Practice, generated and graded by the model.
Two weeks later I added one free Topic Practice session a day, reachable from a mistake in Review. The feedback is what sells the product, and without that session a free user would never see it.
That one session more than doubles what an engaged free user costs: from about $0.70–0.84 to about $1.72–1.86 a month. The Daily Test part uses measured token counts measured; the practice session is still an estimate estimated.
Show chart data
| Free user, 30 days | Cost per month | Provenance |
|---|---|---|
| Daily Test only | $0.70–0.84 | Measured token counts × list price |
| Daily Test + one free practice session a day | $1.72–1.86 | Daily Test part measured, practice part estimated |
How I'll know. Two analytics events record when a free user spends the session and when they hit the limit. After four weeks the question is simple: do free users who use it convert more often than those who don't? If not, the allowance goes down. It is a single constant in the code.
The paywall that wasn't there
- First framing
- The Review screen forgot to check whether the user has Premium.
- Actual problem
- The check lived in navigation, not where the money is spent.
On 15 September a device test showed that a free user could reach paid practice. From Review, tapping a weak spot and then "Practice this" started a real, billed generation with no subscription check at all. I had noticed the risk ten days earlier, written it down, and deferred it.
The quick fix was another copy of the check, this time on the Review screen. But the Home screen's locked cards were only a navigation guard: they stopped a tap, they didn't protect the thing that costs money. There is exactly one function in the app that generates a practice set. The check moved inside it, and that function now requires the subscription service as a mandatory dependency, not an optional flag a caller can forget. Every path goes through the same gate, including paths that don't exist yet.
The pattern paid off a week later. Apple's App Review rules require explicit permission before personal data goes to a third-party AI. The permission screen went into the same function, in front of the same gate, and I didn't have to find every entry point again.
What it cost. Ten days with a known leak, and no test had covered either screen. How I'll know. This one is structural rather than measured: both entry points now have tests that exercise the gate.
The cap that was really a margin
- First framing
- Two limits conflict. Raise the server limit, or lower the session cap?
- Actual problem
- At the planned cap, a heavy subscriber costs more than they pay.
Premium allowed 10 practice sessions a day. Each session uses two server calls, and the proxy that protects the API key allows 15 calls per device per day. So a heavy subscriber would hit a generic "come back tomorrow" after about seven sessions. The options on the table were to raise the server limit to about 25 or lower the cap to 7.
Framed that way, it was a configuration question. Framed as money, it wasn't. At about $0.034 per session estimated, 10 sessions a day is about $10.20 a month. The annual plan nets about $3.54 a month at the 15% commission of Apple's Small Business Program, which approved GrammarLens in September 2026. Break-even is about 3.5 sessions a day.
Show chart data
| Sessions per day | Model cost per month (estimated) | Note |
|---|---|---|
| 1 | $1.02 | |
| about 3.5 | $3.54 | Break-even: about 3.5 sessions a day |
| 5 | $5.10 | New cap: 5 |
| 10 | $10.20 | Old cap: 10 |
| $3.54 | Annual plan, net per month: $3.54 | |
| $5.09 | Monthly plan, net: $5.09 |
My first instinct was 3. I settled on 5 and left prices unchanged at $5.99 a month and $49.99 a year. A cap is easier to raise after launch than to cut. Five is still above break-even for an annual subscriber who maxes it out every day. The bet is that almost nobody does, and that the average, not the maximum, sets the margin.
One rule came out of this: the word "unlimited" never appears in Premium copy. The cap is real, so the claim would be false.
How I'll know. The proxy now logs token counts for every call. If a real session costs less than the estimate, the cap goes up.
The first Daily Test
- First framing
- The first test takes more than 20 seconds to load.
- Actual problem
- Why generate the first test at all?
Every new user meets the same first screen, and it took more than 20 seconds to load. That looks like a latency problem, and my first fix treated it as one: start generating the set in the background the moment the user taps "Get started". It still wasn't fast enough.
The better question was why this set was generated at all. It is the one screen every user sees, so it is where an odd question or a wrong answer key costs the most. Generating it meant a wait, an API call, and an answer key nobody had read.
I wrote the first test by hand instead: five questions, instant, no API call. The background preload I had built that morning was removed the same day.
The saving turned out smaller than it looked. Finishing a test starts preparing the next day's set in the background, so the next day opens instantly. That means every install that never comes back still pays for one generation, about $0.025 at measured token counts measured.
How I'll know. Completion and scores on the fixed set compared with generated ones. The app records which kind of set each test was.
A promise the product didn't keep
- First framing
- A wrong answer shows no explanation. Missing text.
- Actual problem
- The store page promises something the product doesn't do.
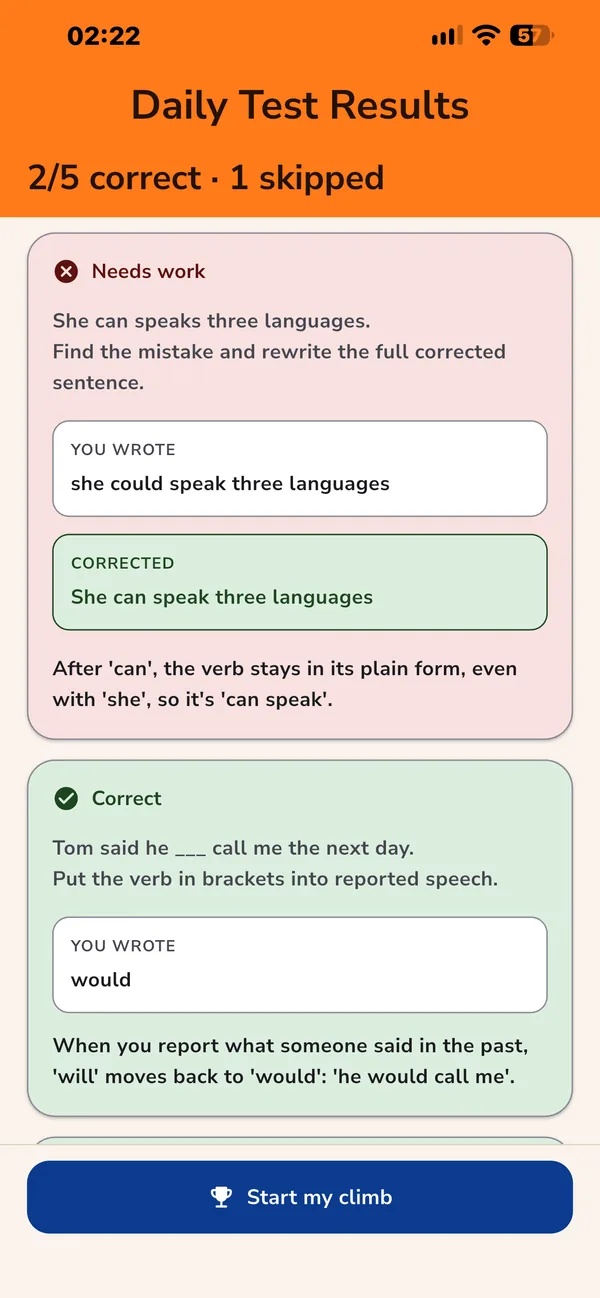
On the day of submission I noticed that a wrong Daily Test answer showed the correct answer and nothing else. My first read was a missing piece of text. It wasn't. The Daily Test is graded on the device, and the generated set only carried comments for the wrong answers the model had predicted. Correct answers, skipped ones and any unexpected mistake got no explanation at all.
Meanwhile the App Store description said you see why each answer was right or wrong. So did the first version of this page. I had written that promise twice without checking it against the product.
The fix was one explanation per question, generated in the same call as the questions, under 25 words. That needed more room, so the Daily Test got its own output budget: the worst response went from using 80% of a 2,048-token limit to using 49% of a 3,072-token one measured. The average explanation dropped from about 29 words to 20. Five of 25 still ran slightly over the limit, which I accepted: nothing depends on the exact length.
Show chart data
| Version | Limit | Worst response | Headroom |
|---|---|---|---|
| Before explanations | 2,048 | 1,632 | 20% |
| With explanations, own limit | 3,072 | 1,496 | 51% |
What it cost. A Daily Test set now costs about $0.023–0.028 measured, above my earlier $0.021 estimate. How I'll know. I've seen the new explanations on a device only on the hand-written first test so far; the first generated set on a real device is the next check.
3. Where to ask for money
Placing the paywall produced three decisions, and one mistake.
After the win, not after the list. The first test used to end in a paywall card on the result screen, right after the first score and before anything had visibly changed. I moved it. Now the result screen ends in one button, "Start my climb". The user's avatar climbs its first step on Home, and the Premium screen appears about 600 ms later, once. The hypothesis is that the moment after a visible win converts better than the moment after a list of results. It is a hypothesis, not a finding.
-
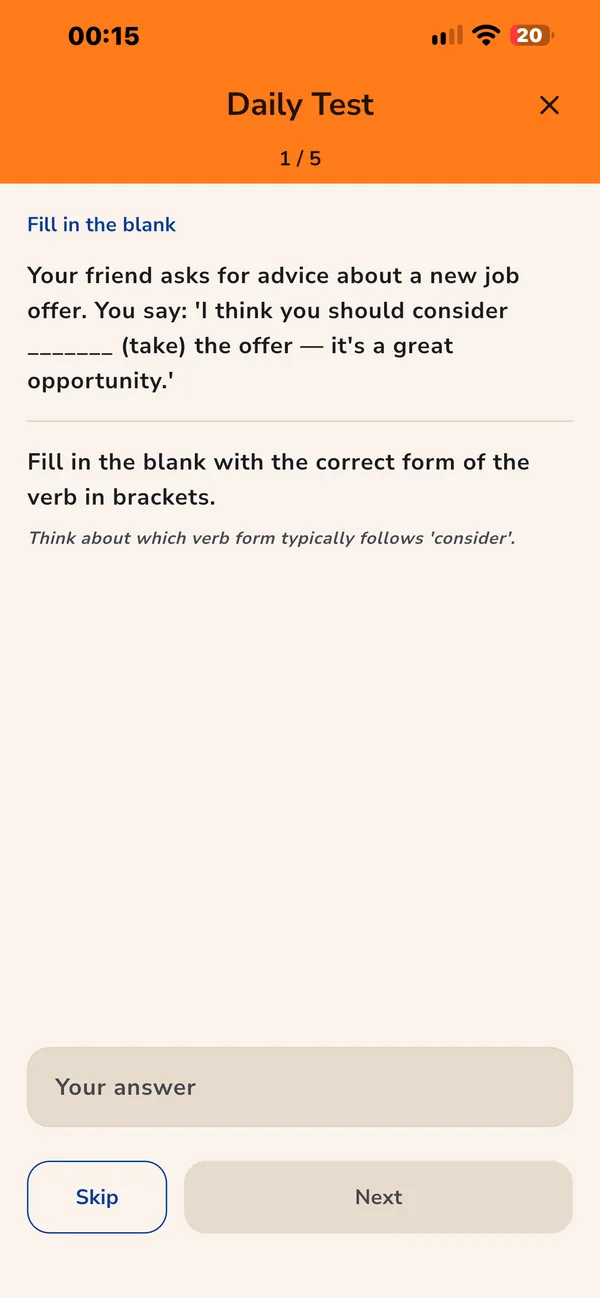
A hand-written first test, no loading. -
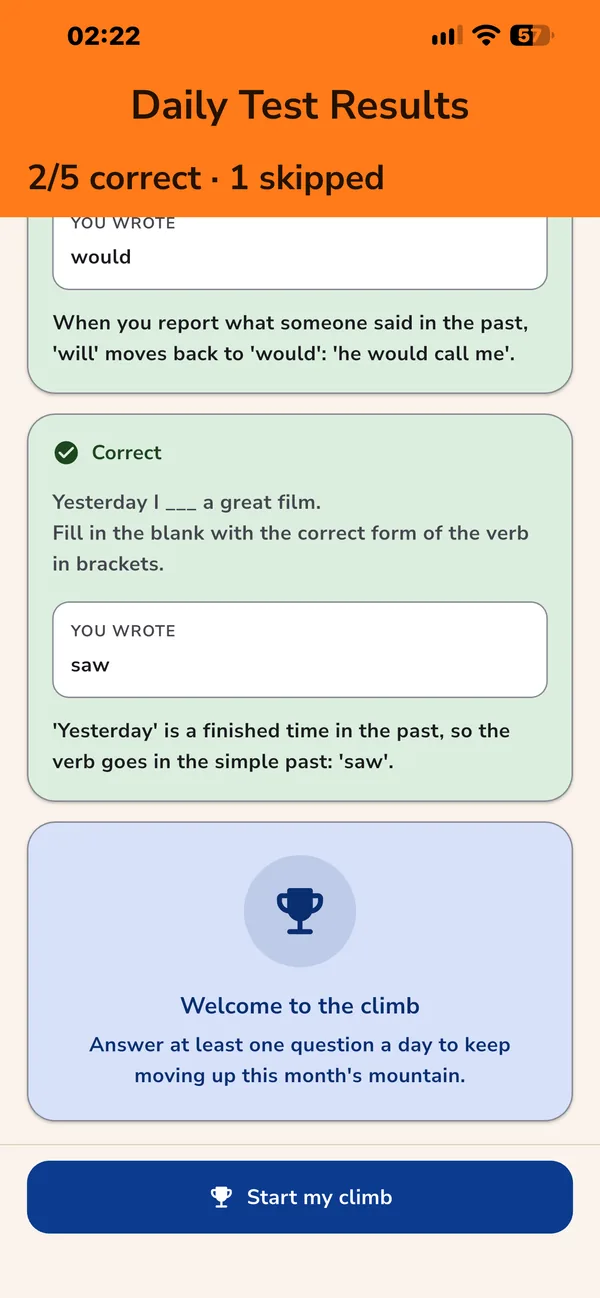
One button: Start my climb. -
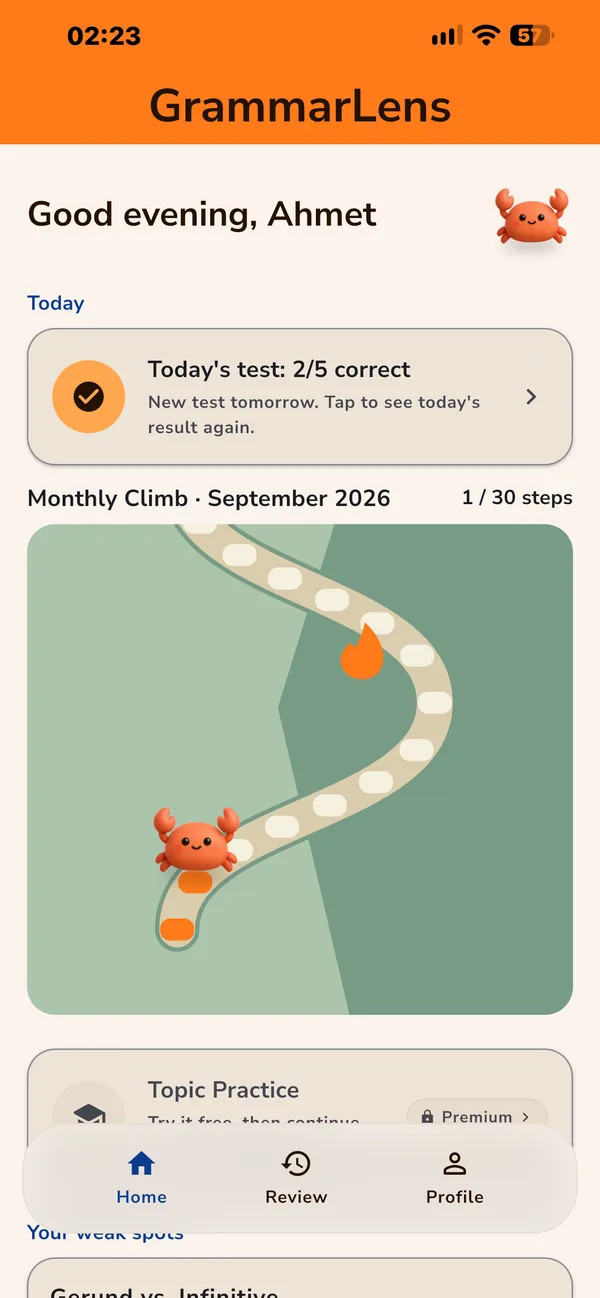
The avatar takes its first step. -
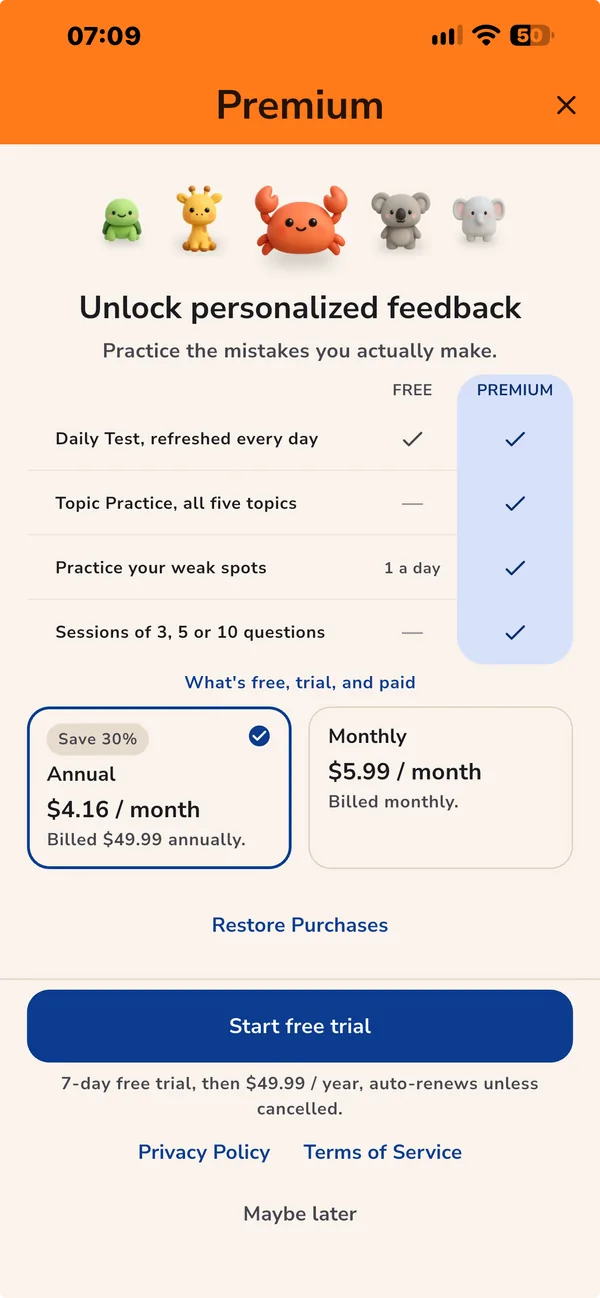
The Premium screen. On day one it opens once, right after the climb.
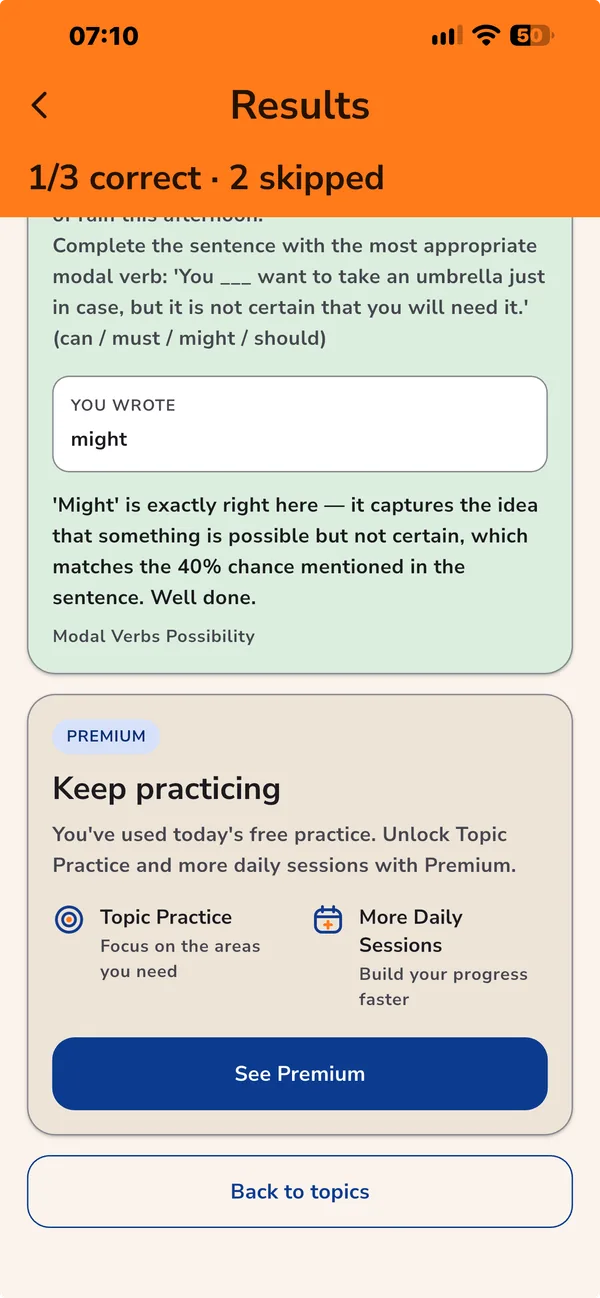
An exit stays an exit. A free user who has used the day's practice session lands on a results screen whose only way out was "Back to topics". The obvious move was to make that button open the paywall. I didn't: a button that says one thing and does another is a dark pattern, and someone who wants to leave shouldn't have to get past a sales pitch to do it. Instead, the screen got an offer card showing what Premium adds, with its own "See Premium" button. "Back to topics" stays exactly as it was, underneath.
A smaller cut belongs here too. I added a row to the Premium comparison table showing the daily session difference, free versus Premium. On a 375-point-wide phone it pushed the plan cards almost off the screen: their visible part fell from 78 points to about 30 at default text size, and to nothing at large text measured. I reverted it the same day. Hiding the thing people buy to explain the thing they'd get is the wrong trade. The cost is a real gap: the offer card promises more daily sessions, and the Premium screen can't show it yet.
The mistake: two variables in one release. The new first-day paywall shipped in the same release as Monthly Climb, the habit layer. My own gamification spec had warned against exactly this: launched together, their effects can't be separated. There is no earlier baseline to compare against. So when I read first-day conversion after launch, I'll be able to report it, but not to say how much of it comes from the timing. I defined what to build before I defined what I needed to learn.
4. What I'd do differently
I fixed measurement and broke it somewhere else. The first version of this page said measurement should have come first. This time it did: analytics with a written plan, and token logging on every API call, all live before submission. Then I shipped two changes whose effects I wanted to measure in the same release. Instrumentation is necessary, but it isn't the same as a measurable plan.
Stale documents don't stay in one place. The first version of this page described a line in my own documents claiming the free tier cost approximately nothing, which had survived after the reasoning behind it was disproved. The same claim survived in the project's README until the day I submitted. A documentation audit after submission found 21 status lines across the docs that no longer matched reality. The fix I've adopted is structural: the current state lives in one document, and old plans get a dated "historical" note instead of line-by-line edits nobody keeps up.
Make the irreversible decisions early. The bundle identifier sat as a placeholder for months and surfaced as a launch blocker. Product identifiers can't be renamed once created. The same applied at the end: Apple doesn't let an app drop iPad support after a version ships, so I kept iPad on purpose, because education apps live on school tablets, and locked the app to portrait. The price is Split View on iPad. None of these is hard. All of them are annoying to discover late.
Reversing a decision is cheaper than defending it. I cancelled a planned private testing round because seven people had already used the core loop. I cut two advertised but unbuilt features from the purchase screen, because a paid surface listing things that don't exist is both an App Store rejection risk and a lie. I reverted the comparison-table row within a day. Each reversal is written in the project log with its date and the reasoning that replaced the old one.
How I worked. AI coding agents wrote the code; my job was the decisions. Any change that involved a judgment call started with a read-only report from the agent (the options, the measurements, the risks) and no code until I'd decided. At submission the project had 883 app tests and 70 server tests. Keeping the decision record is the part I'd repeat without changing anything.
5. Status, and how I'll know
GrammarLens 1.0 was submitted to App Store review on 24 September 2026, together with its two subscriptions. It is not approved yet. Release is manual, so approval won't publish it on its own.
The first four weeks after release are for reading, not building. The questions:
- What does a Daily Test and a practice session really cost? The token log replaces every estimate on this page.
- Do free users who use the daily practice session convert more often than those who don't?
- Does the hand-written first test perform differently from generated ones?
- How does conversion differ by where the paywall appeared? Read with the caveat from section 3.
The next product decision is already framed. Instead of every device generating its own Daily Test, one set a day would be generated for everyone, which removes most of the Daily Test's cost. What's still open is how answers get explained, which day boundary to use across time zones, and what happens if the daily generation fails. That decision waits for the token data.
This page will get a results section once there are results.